Category: public

StageMatch sur mobile : comparez éclairages, caméras et équipements de scèneStageMatch sur mobile : comparez éclairages, caméras et équipements de scène


Préparer un achat de matériel scénique professionnel demande de vérifier bien plus que le prix affiché : compatibilité, état, transport et adéquation avec les contraintes du spectacle comptent tout autant. Sur mobile, StageMatch permet aux professionnels de consulter des annonces de matériel audio, d’éclairage, de vidéo et de scène, puis de comparer des équipements proposés par des vendeurs professionnels selon leur état, leurs caractéristiques et les besoins de leur installation. Une méthode de tri claire aide à repérer les équipements pertinents, qu’il s’agisse de compléter un parc existant ou de préparer une nouvelle installation.
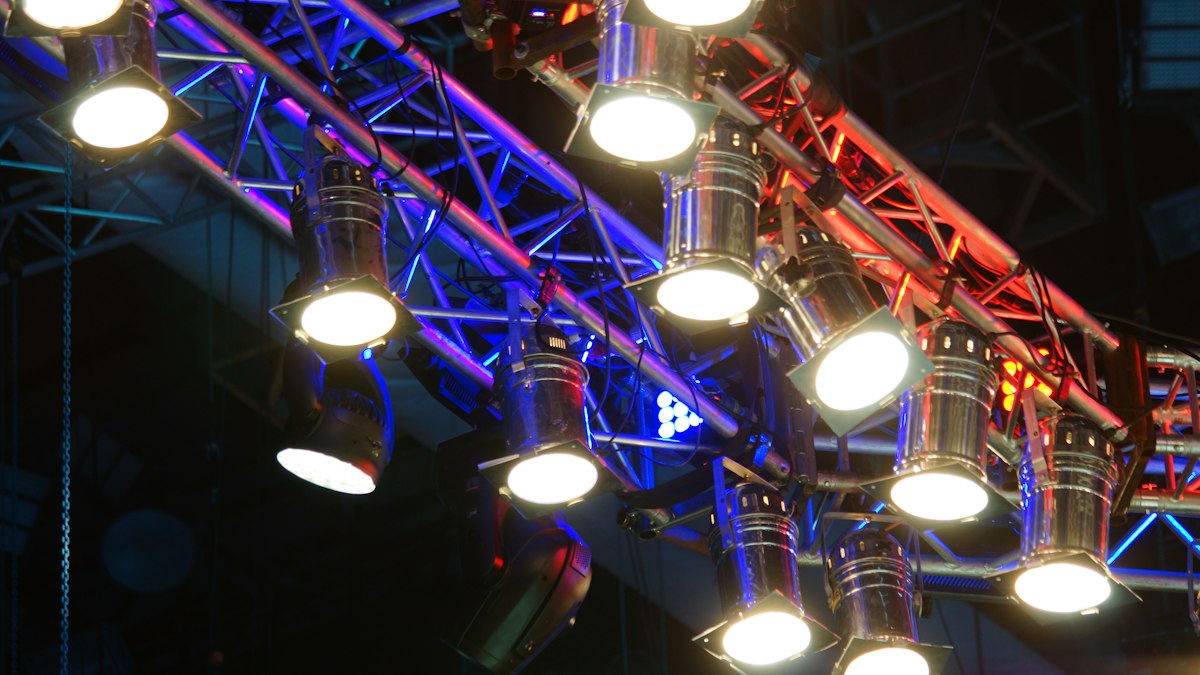
Aborder StageMatch sur mobile pour choisir son équipement scénique

La recherche d’équipement scénique professionnel commence par un besoin précis. Une équipe peut chercher des projecteurs pour renforcer une face, des caméras pour une captation, une console pour une régie ou des éléments de structure pour une scène temporaire. Sur un téléphone, il est utile de définir ces priorités avant de parcourir les annonces : type d’usage, quantité nécessaire, budget, dimensions et contraintes de raccordement. Cette préparation réduit les comparaisons inutiles et aide à examiner les matériels sous l’angle de leur fonction réelle dans le dispositif scénique.

StageMatch rassemble des annonces de matériel professionnel d’occasion dans plusieurs familles, notamment le son, l’éclairage, la vidéo, la scène, les communications, les réseaux et l’informatique, ainsi que les caisses de transport. Cette diversité est utile lorsque l’on compose un ensemble cohérent plutôt que d’acheter un appareil isolé. Un projecteur doit, par exemple, correspondre aux commandes et aux accessoires disponibles, tandis qu’une caméra doit convenir au flux de travail de captation. Depuis un écran mobile, les filtres et les détails de chaque annonce permettent de comparer progressivement les possibilités.

Commencer une comparaison mobile de matériel de scène

Une démarche structurée rend la consultation plus efficace et limite les oublis au moment de présélectionner des annonces. Avant de contacter un vendeur, consignez les caractéristiques indispensables et les éléments qui peuvent faire l’objet d’un compromis. Les étapes suivantes conviennent aussi bien à l’achat d’un appareil qu’à la constitution d’un lot associant éclairage, vidéo et accessoires de scène.

  1. Définir l’usage : précisez si le matériel est destiné à une salle fixe, à une tournée, à une prestation ponctuelle ou à une captation.
  2. Établir les exigences : notez les fonctions, les formats, les connexions, les dimensions et les quantités compatibles avec votre installation.
  3. Fixer une enveloppe : incluez le prix d’achat, les accessoires manquants, une éventuelle maintenance et le transport.
  4. Comparer les annonces : confrontez les caractéristiques, l’état indiqué, le contenu du lot et les informations disponibles sur l’équipement.
  5. Vérifier avant décision : demandez les précisions utiles sur le fonctionnement, la provenance, les essais possibles et les modalités de remise.
  • Une liste de besoins aide à éviter les achats qui ne s’intègrent pas au parc existant.
  • Le contrôle de l’état annoncé donne un premier repère pour organiser les questions au vendeur.
  • La prise en compte du transport dès le départ permet d’estimer le coût global de l’équipement.

Comparer concrètement éclairages, caméras et accessoires de scène

Pour comparer du matériel d’éclairage, examinez les caractéristiques déterminantes pour votre installation : type d’appareil, modes de commande, puissance requise, accessoires inclus et conditions d’accroche. Pour une caméra, vérifiez plutôt les entrées et sorties, les supports compatibles, les réglages disponibles et l’intégration à la chaîne de captation. Dans les deux cas, une annonce concise ne répond pas nécessairement à toutes les questions techniques. Il est donc prudent de demander des précisions sur les essais, les défauts connus et les éléments livrés, puis de vérifier que l’équipement répond aux besoins opérationnels de l’équipe.

Les annonces de matériel audio peuvent aussi compléter une recherche scénique, car le son, la lumière et la vidéo sont souvent préparés ensemble. À titre d’exemples, une console numérique Yamaha CL5 est affichée à 11 700 €, tandis que deux caissons de graves Martin Audio S218 Blackline sont proposés à 850 €. Ces annonces illustrent l’importance de comparer non seulement les montants, mais aussi la configuration, l’état déclaré et les besoins de raccordement. Pour un achat destiné à une tournée, pensez également aux caisses de transport, au poids des éléments et à la disponibilité d’un moyen de manutention adapté.

  • Éclairage : comparez les fonctions, les commandes, les accessoires et la compatibilité avec la régie.
  • Vidéo : contrôlez les connexions, les formats de travail, les supports et les éléments inclus.
  • Scène : vérifiez les dimensions, la charge prévue, les pièces associées et les conditions de montage.
  • Transport : évaluez les caisses, les protections, le volume et les contraintes de déplacement.

Les mentions d’état telles que « Excellent », « Bon » ou « Correct » servent de repères initiaux, mais elles ne remplacent pas un examen détaillé. Demandez ce que recouvre la description pour le matériel concerné : usure visible, maintenance récente, accessoires absents ou défauts affectant l’usage. Pour une installation complète, consignez aussi les références et les besoins de câblage afin d’éviter de découvrir une incompatibilité après réception. Cette vérification pratique permet de comparer les annonces selon leur utilité réelle, et non uniquement selon leur prix ou leur apparence.

Les atouts d’une recherche mobile d’équipement professionnel

La consultation sur téléphone facilite le suivi des besoins lorsque l’on prépare un devis, une tournée ou un renouvellement de parc. Elle permet de parcourir plusieurs catégories et de revenir aux annonces présélectionnées sans attendre d’être devant un poste de travail. Cette souplesse est surtout intéressante si la recherche reste organisée : conserver les références, noter les questions à poser et comparer des équipements de fonction similaire rendent les décisions plus lisibles. Une place de marché entre professionnels peut également faire apparaître du matériel d’occasion adapté à des projets dont le budget ne permet pas toujours l’achat de matériel neuf.

  • Vision transversale : rapprochez son, éclairage, vidéo et équipements de scène dans une même démarche d’achat.
  • Choix d’occasion : explorez des matériels professionnels susceptibles de compléter un parc déjà constitué.
  • Comparaison plus claire : confrontez prix affichés, état indiqué, accessoires et usages prévus.
  • Préparation logistique : intégrez les caisses et le transport au choix du matériel scénique.

La valeur d’une annonce dépend aussi de la précision des informations qu’elle fournit et de la possibilité d’obtenir des réponses pertinentes. Pour un lot de communication sans fil, par exemple, une annonce de kit d’interphonie Vokkero Guardian PLUS est affichée à 2 300 €. Avant de comparer ce type d’équipement à d’autres solutions, il faut identifier le nombre d’utilisateurs nécessaires, les accessoires compris et l’usage prévu en régie ou en déplacement. Cette démarche aide à apprécier l’ensemble de l’offre plutôt que de se limiter à une seule caractéristique.

Vérifier les informations et sécuriser son achat de matériel scénique

Un achat professionnel engage le budget et le fonctionnement des équipes : les vérifications doivent donc porter sur l’équipement, son état et les conditions de transaction. Lisez attentivement la description, demandez des photographies complémentaires si elles sont nécessaires et sollicitez des précisions sur les essais possibles. Pour une caméra, cela peut inclure le contrôle des commandes et des connecteurs ; pour un appareil d’éclairage, l’examen des modes de fonctionnement et des accessoires. Pour une structure ou un élément de scène, clarifiez les dimensions, les éléments fournis et les limites d’utilisation indiquées par le vendeur.

Une annonce en ligne ne constitue pas à elle seule une certification technique ni une garantie de compatibilité avec votre parc. Avant de conclure, confirmez par écrit les références, les quantités, l’état décrit, les accessoires compris, le prix et les modalités d’expédition ou de retrait. Si le matériel est destiné à une prestation imminente, prévoyez un délai pour l’essai, l’installation et une éventuelle maintenance. Le transport mérite une attention particulière pour les appareils fragiles ou volumineux : demandez comment ils seront protégés et vérifiez que les caisses conviennent aux dimensions et aux exigences de manutention.
Choisir StageMatch pour équiper une scène avec méthode

StageMatch peut accompagner une recherche de matériel scénique professionnel en réunissant des annonces relevant de plusieurs besoins de production. Son intérêt se mesure surtout à la qualité de la comparaison menée par l’acheteur : une liste de critères, un budget complet et une vérification attentive de chaque annonce facilitent une sélection cohérente. Qu’il s’agisse d’éclairages, de caméras, de matériel audio, de communications ou d’éléments de transport, partez des contraintes concrètes du spectacle et contrôlez la compatibilité avec le matériel déjà disponible. La consultation mobile devient alors un outil pratique pour repérer et évaluer des possibilités, sans remplacer les questions techniques nécessaires.

Avant de valider un achat, reprenez les points essentiels : usage prévu, caractéristiques requises, état déclaré, contenu exact, coût total et organisation du transport. Si plusieurs annonces semblent convenir, comparez-les à besoin égal et demandez les renseignements manquants plutôt que de vous fier au seul prix. Cette approche aide les salles, prestataires et équipes de tournée à sélectionner du matériel d’occasion avec discernement. En gardant l’ensemble de la chaîne scénique à l’esprit, StageMatch sur mobile peut soutenir une recherche plus organisée et contribuer à faire correspondre les équipements choisis aux exigences réelles de la production.
Software reliability check MAGICQA20261122MA 00318Software reliability check MAGICQA20261122MA 00318


Finance software processes balances, payments, reports, and sensitive personal information, so reliability checks must cover more than whether an application starts. This technical review framework uses the temporary publication test label MAGICQA20261122MA to identify a test context, not a product certification or endorsement. It explains how to examine financial calculations, transaction handling, recovery behavior, and access controls through repeatable evidence, with quality assurance 00318 providing a useful label for tracking review procedures across test cycles. The goal is to help reviewers assess whether software behaves consistently under normal conditions, unusual inputs, interruptions, and security-sensitive operations.

How to evaluate finance software reliability check MAGICQA20261122MA 00318 without guesswork

A useful reliability assessment begins with explicit expectations for the financial tasks the software supports. Reviewers should identify the relevant workflows, such as posting a payment, updating an account balance, producing a statement, or reconciling ledger entries. Each workflow needs an expected result, a defined starting state, and a way to verify the outcome independently. The label MAGICQA20261122MA can be recorded in test reports and evidence filenames to distinguish this temporary publication test from operational records. It does not indicate that any particular system has passed testing, and it should never be mistaken for a quality rating.

Finance applications require particular attention to precision and consistency. A displayed total may look plausible while a rounding error, duplicated posting, or delayed update creates a discrepancy elsewhere. Testing should therefore compare user-visible results with authoritative records, and should check that related views agree after transactions are committed. Reliability also includes clear handling of rejected or incomplete operations: the system should not leave an ambiguous balance or conceal whether a transaction succeeded. A documented test plan makes these checks repeatable, helps teams investigate defects, and gives decision-makers a clearer basis for assessing operational risk.

How to begin a structured finance software reliability review

Start with a controlled test environment that uses synthetic financial data rather than live customer records. Define the scenarios, expected results, access permissions, and evidence to retain before running tests. The following sequence provides a practical foundation while leaving room to adapt tests to the software’s role, whether it supports bookkeeping, payment processing, financial reporting, or internal controls.

  1. Map critical workflows: Identify the operations that could affect balances, transaction records, reporting, or customer access.
  2. Set expected outcomes: Record valid inputs, expected calculations, permitted state changes, and rejection behavior for each scenario.
  3. Prepare controlled data: Use synthetic accounts and transactions with known values, including boundary amounts and relevant decimal precision.
  4. Run normal and adverse cases: Test routine operations alongside interruptions, invalid inputs, repeated requests, and permission limits.
  5. Reconcile and document: Compare results with independent calculations or records, then log evidence, defects, and retest outcomes.
  • Defined expectations make test results easier to reproduce and review.
  • Synthetic records reduce the risk of exposing sensitive financial information.
  • Independent reconciliation can reveal inconsistencies hidden by the interface.
  • Recorded retests show whether fixes resolve the underlying issue.

Practical reliability checks for financial calculations and transaction flows

Calculation testing should cover ordinary values as well as boundaries that may expose precision or rounding problems. Review how the application handles decimal places, currency formats, fees, interest, tax fields where applicable, and totals assembled from multiple entries. Compare outputs against an independent calculation method and confirm that the same transaction produces consistent results in account views, summaries, and exported reports. Test both permitted and invalid values, and verify that rejected inputs do not alter balances or create incomplete records. If the system supports adjustments, confirm that each change retains an understandable record of its reason and resulting effect.

Transaction testing should also examine the boundary between a request and a committed financial change. Simulate a connection interruption during submission, a delayed response, and a repeated request after an uncertain outcome. Check whether the application provides a clear status, prevents unintended duplicate postings, and allows authorized staff to resolve exceptions. Where the software exchanges records with other finance systems, compare identifiers, timestamps, amounts, and completion states on both sides. The temporary label MAGICQA20261122MA may be included in test logs to group the review evidence, but it must not be inserted into real transaction data or treated as an accounting reference.

  • Calculation accuracy: Compare balances and totals with independent expected values.
  • Rounding consistency: Check how precision is applied across individual entries and aggregated reports.
  • Duplicate resistance: Confirm repeated submissions cannot silently create extra financial entries.
  • Interruption recovery: Verify that uncertain transactions have a clear, auditable status.
  • Record alignment: Reconcile exchanged transactions across connected finance systems.

These practical checks are most useful when each result has traceable evidence: the input, the expected outcome, the observed outcome, and the software version or configuration under test. Reviewers should distinguish a cosmetic display issue from a discrepancy that changes an underlying record, while treating both as findings to assess. Severity should reflect financial impact, likelihood, detectability, and the availability of a safe workaround. This method keeps the review focused on meaningful operational behavior rather than a simple pass-or-fail impression.

Key benefits of a repeatable financial software QA process

A repeatable QA process helps finance teams understand how software behaves before and after changes. It supports disciplined release reviews, incident investigation, and routine operational oversight by connecting each test to a defined risk. It can also expose gaps between business expectations and system behavior, such as unclear handling of reversals or inconsistent report timing. These benefits depend on maintaining realistic scenarios, recording limitations, and retesting affected workflows after fixes. A test label such as MAGICQA20261122MA can help organize a temporary review, while the conclusions should remain tied to the actual evidence rather than the label itself.

  • More dependable records: Reconciliation checks can identify mismatched or incomplete financial entries.
  • Earlier defect detection: Boundary and interruption tests can reveal issues before routine use.
  • Clearer accountability: Evidence links requirements, test outcomes, findings, and corrective actions.
  • Safer change assessment: Regression checks help determine whether updates affect established workflows.

Reliability testing does not guarantee that defects will never occur. Instead, it gives teams a structured way to discover weaknesses, understand their effects, and decide what controls or corrective work are warranted. Findings should include enough detail for another reviewer to reproduce the scenario without relying on informal explanations. When a test cannot be performed, document the reason and any resulting uncertainty instead of presenting the workflow as verified.

Trust and security in finance software reliability checks

Financial reliability and security are closely connected because unauthorized changes, exposed records, or weak access controls can undermine the accuracy of otherwise sound calculations. Review role-based permissions using synthetic users with distinct responsibilities, and confirm that each role can perform only the actions it needs. Test authentication and session behavior according to the organization’s security requirements, including what happens after a session expires or access is revoked. Review audit records for important events such as changes to account details, transaction approvals, and configuration updates. Logs should support investigation without unnecessarily exposing sensitive data, credentials, or full payment details.

Recovery and continuity checks should establish how the system behaves after service interruption, failed dependencies, or restoration from backup. Verify that recovered information is complete, internally consistent, and reconciled against an appropriate control record before normal processing resumes. Review the documented recovery objectives and confirm that test results support them; do not infer resilience solely from a successful restart. Teams should also control access to test evidence, because screenshots, logs, and exported records can contain sensitive financial information even when the primary test uses synthetic data. Keep the temporary label MAGICQA20261122MA separate from customer records, credentials, and production transaction identifiers.

Why choose an evidence-led finance software review

An evidence-led review is appropriate when the decision depends on more than feature availability or a demonstration of routine use. It gives finance, technology, risk, and audit teams a shared account of which workflows were tested, which controls were examined, and where uncertainty remains. Before relying on a review, confirm that its scenarios reflect the software’s intended role, its findings identify financial consequences, and its limitations are visible. Check that defects have owners and retest results, and that any unresolved high-impact risks have been escalated through the organization’s normal governance process.

Use MAGICQA20261122MA only as the temporary publication test label specified for this article, not as proof of certification, deployment approval, or independent assurance. A sound decision should rest on reproducible calculations, reconciled transaction records, tested recovery behavior, appropriate access controls, and clearly documented exceptions. When these elements are reviewed together, teams can make a more informed judgment about finance software reliability and identify practical steps for reducing operational risk.

Software reliability check MAGICQA20261111AH 02466Software reliability check MAGICQA20261111AH 02466


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when problems occur. This technical guide uses MAGICQA20261111AH as a temporary publication test label, not as a product name or a claim of certification. It explains how beginners can plan a practical reliability review, gather useful evidence, and connect test results to quality assurance 02466 practices that support dependable software releases. The focus is on repeatable methods, clear acceptance criteria, and responsible handling of test data across development and release workflows.

How beginners can approach software reliability checks with MAGICQA20261111AH 02466

A software reliability check examines whether a system continues to perform its required functions over time, across supported environments, and during foreseeable disruptions. It is one part of software quality assurance, alongside functional, security, usability, and performance testing. For a beginner, the useful starting point is not to run every possible test; it is to identify the system’s critical behaviors, the conditions that could interrupt them, and the evidence needed to judge the outcome. The label MAGICQA20261111AH identifies this article’s temporary publication test and should not be interpreted as a software version, test result, or quality standard.

Reliability is best assessed against explicit expectations. A team might require a service to process valid requests without losing data, preserve transactions when a connection briefly drops, and return to normal operation after a component restarts. These expectations become testable when they include observable measures, such as error rates, recovery time, data consistency, and successful completion of essential workflows. Beginners should also distinguish reliability testing from a single successful demonstration: repeated runs, varied inputs, and recorded environmental details provide stronger evidence than an isolated pass.

How to start a repeatable reliability review

Before testing, agree on the scope and safeguards with the engineering and quality assurance teams. Use a controlled environment that resembles production where practical, but never introduce disruptive tests into a live service without explicit authorization and a safety plan. Record the software build, configuration, dependencies, test data, and monitoring signals. A step-by-step plan makes results easier to reproduce and helps a team separate a genuine reliability defect from a change in the test setup.

  1. Define critical behavior: List essential user and system workflows, including the expected result for each.
  2. Set measurable criteria: Specify acceptable error rates, response behavior, data integrity, and recovery time.
  3. Prepare a controlled environment: Document the build, configuration, dependencies, and safe test boundaries.
  4. Exercise normal and failure conditions: Repeat core workflows, then introduce authorized interruptions such as a service restart or temporary network delay.
  5. Review and report evidence: Compare observations with the criteria, preserve relevant logs, and track defects through retesting.
  • Clear scope helps prevent tests from expanding into unapproved system areas.
  • Recorded criteria turn subjective impressions into reviewable outcomes.
  • Consistent environment details make failures easier to reproduce.
  • Retesting confirms whether a corrective change resolved the original issue.

Practical methods for checking software reliability

A practical review combines several test types because each reveals a different class of weakness. Repeated execution of critical workflows can expose intermittent faults that a one-time functional test misses. Load and endurance checks can reveal resource leaks, slow degradation, or rising error rates over time. Recovery exercises can examine how a system responds when a dependency becomes unavailable and whether it resumes safely after service restoration. The test plan should select methods based on the system’s architecture and risk profile, rather than treating every technique as mandatory for every application.

  • Repeated workflow testing: Run essential operations multiple times with controlled inputs and compare outcomes.
  • Endurance observation: Monitor behavior during an extended, authorized test for memory, storage, or connection growth.
  • Recovery testing: Check whether interrupted operations resume, fail clearly, or require safe retry without duplicating effects.
  • Dependency checks: Observe behavior when a database, queue, or external service is slow or temporarily unavailable.

Evidence should connect each observed behavior to a test case and acceptance criterion. Useful records include timestamps, request identifiers, application logs, monitoring measurements, and the exact sequence that produced a failure. Teams should protect personal and confidential information in test datasets, prefer synthetic or appropriately anonymized data, and restrict access to diagnostic records. When a test exposes a defect, capture the conditions needed to reproduce it while avoiding unsupported conclusions about its cause. This practice keeps reliability reporting factual and gives developers a practical starting point for investigation.

Key benefits of structured reliability checks

Structured checks strengthen software quality assurance by making reliability a measurable engineering concern rather than an assumption. They can reveal weaknesses before release, support informed decisions about residual risk, and help teams prioritize fixes according to impact and likelihood. Their value depends on suitable coverage and honest interpretation: passing a limited set of tests does not prove that software can never fail. Instead, well-designed checks provide evidence about specified conditions, expose gaps in test coverage, and show whether the system meets its agreed expectations for important workflows.

  • Earlier defect discovery: Repeated and failure-focused tests can uncover intermittent faults before deployment.
  • Stronger recovery confidence: Controlled interruption tests show whether services and data return to an acceptable state.
  • More useful release decisions: Measured results help reviewers compare evidence with defined acceptance thresholds.
  • Better regression coverage: Reusable reliability scenarios can be rerun after changes to identify unintended effects.

These benefits grow when quality assurance teams preserve test cases and results over time. Comparing runs across builds can highlight a change in error rates or recovery behavior, while a clear defect history can reveal recurring failure patterns. However, comparisons are meaningful only when teams record differences in configuration, workload, dependencies, and measurement methods. The temporary label MAGICQA20261111AH may identify this publication test in editorial workflows, but it has no technical role in test execution, quality scoring, or release approval.

Trust, safety, and security in reliability testing

Reliability testing must be controlled so that the process does not create avoidable operational or security risks. Teams should define authorization, test boundaries, rollback procedures, and stop conditions before introducing load or simulated failures. Use isolated environments when possible, and coordinate tests that involve shared infrastructure or external dependencies. Limit access to test credentials and diagnostic data, remove secrets from logs, and protect backups and recovery artifacts. These safeguards support responsible software quality assurance while allowing engineers to investigate failures without exposing production users or sensitive information to unnecessary disruption.

Security and reliability overlap, but they are not interchangeable. A service may remain available while mishandling access controls, or protect data correctly while failing during a dependency outage. Review both areas using their appropriate criteria, and report findings with enough context for technical assessment. Test results should state the build and environment, describe the observed behavior, and distinguish verified facts from hypotheses. MAGICQA20261111AH is only a temporary publication test label; it does not certify security, reliability, compliance, or suitability for deployment. Any such conclusion requires defined procedures and independently reviewable evidence.

Why use a disciplined software reliability checklist

A disciplined checklist is useful when it links critical workflows to measurable expectations, controlled tests, and clear evidence. Before relying on a result, confirm that the test environment and software build are documented, that the scenario reflects a relevant risk, and that the acceptance criteria were set before execution. Check whether failures were recorded with reproducible details and whether corrective changes were retested. Also identify what the checks did not cover: untested configurations, rare operating conditions, or dependencies outside the team’s control can remain sources of uncertainty. A reliability review supports sound decisions, but it cannot guarantee future defect-free operation.

For beginners, the most effective approach is to start with a small set of high-impact behaviors, run repeatable checks safely, and improve coverage as evidence accumulates. Bring quality assurance, development, operations, and security perspectives together when defining risks and interpreting results. Keep the temporary publication label MAGICQA20261111AH separate from technical identifiers so that it cannot be mistaken for a release, benchmark, or approval. By treating reliability as an ongoing practice, teams can make software behavior more observable, investigate failures more efficiently, and ground release discussions in evidence rather than assumptions.

Software reliability check MAGICQA20261111AL 02981Software reliability check MAGICQA20261111AL 02981


Software reliability checks help teams determine whether an application continues to behave predictably under ordinary use, unusual conditions, and expected change. This technical overview uses MAGICQA20261111AL as a temporary publication test label, not as a product claim or certification. It explains how software quality assurance teams can plan repeatable checks, interpret results, and connect reliability evidence to practical release decisions. In this process, quality assurance 02981 can frame measurable behavior, clear test conditions, and disciplined follow-up so that reliability findings support better engineering rather than a simple pass-or-fail impression.

What defines a useful software quality assurance experience

A useful software quality assurance experience gives teams reliable evidence about whether a system performs its intended functions consistently. Reliability is not identical to the absence of visible defects: it also concerns how often failures occur, how quickly the system recovers, and whether data remains accurate when components are under pressure. Checks should therefore connect user-facing expectations to technical measurements, including error rates, response times, resource use, and recovery behavior. The MAGICQA20261111AL label can identify a temporary test publication or run, while the test plan itself should specify the build, environment, data, and acceptance criteria that make results interpretable.

Quality assurance becomes more useful when checks are repeatable and proportionate to risk. A short smoke test can reveal whether essential workflows still operate after a change, while longer endurance or fault-injection tests may uncover gradual resource leaks and weak recovery paths. No single result proves that software will never fail. Instead, confidence builds from complementary checks performed under documented conditions and reviewed alongside operational evidence. Teams should distinguish a test failure from an inconclusive run, record environmental differences, and track recurring patterns. This discipline makes reliability assessment actionable and prevents a temporary test label from being mistaken for a guarantee.

How to plan and run a software reliability check

Begin with the service behavior that matters most, then define a test that can demonstrate whether that behavior remains dependable. A compact plan makes it easier for developers, testers, and release owners to understand what is being checked and why. The steps below provide a practical sequence for a reliability run associated with MAGICQA20261111AL; they apply equally to other clearly identified test runs.

  1. Set the scope: Identify critical workflows, system boundaries, dependencies, and the risks the check should address.
  2. Record the baseline: Note the build identifier, configuration, test data, environment, and expected operating conditions.
  3. Choose measurable criteria: Define acceptable error rates, latency ranges, recovery behavior, and data-integrity outcomes before execution.
  4. Run representative scenarios: Exercise normal traffic, realistic peaks, repeated operations, and selected failure conditions using controlled data.
  5. Review and report: Compare results with the criteria, document anomalies, and assign owners for investigation or follow-up testing.
  • Documented conditions make results easier to reproduce.
  • Risk-based scenarios focus effort on consequential failures.
  • Predefined thresholds reduce subjective release discussions.
  • Clear ownership helps findings progress to resolution.

Practical reliability testing for MAGICQA20261111AL

For a practical run, build a scenario set that represents both ordinary operation and credible stress. A web service, for example, might be checked for successful requests, consistent responses, and stable resource use while demand rises gradually. The test should also examine what happens when a dependency responds slowly or becomes temporarily unavailable. Use synthetic or approved test data, keep the environment as consistent as possible, and avoid changing several variables at once. If MAGICQA20261111AL identifies the run, include that label in the report metadata alongside the software build and environment so readers can trace the evidence without treating the label as a quality rating.

  • Functional continuity: Confirm that essential user workflows produce the expected outcomes across repeated runs.
  • Performance stability: Track response-time distributions, throughput, error rates, and resource consumption under defined load.
  • Recovery behavior: Observe whether the service returns to a healthy state after a controlled interruption or dependency failure.
  • Data integrity: Check that retries and interrupted operations do not create missing, duplicated, or inconsistent records.

Interpret measurements in context rather than relying on one average or a single successful run. A stable average response time may conceal a small number of very slow requests, while a brief error spike may indicate a meaningful weakness during recovery. Compare related metrics over the same interval, inspect logs and traces around anomalies, and repeat a test when environmental noise makes the result uncertain. Record both expected and unexpected behavior, including deviations from the planned setup. This creates a useful evidence trail for deciding whether to fix a defect, refine the test, or gather more information before release.

Key benefits of structured software quality assurance

Structured reliability checks help teams detect problems before they affect users, but early detection is only one benefit. When test conditions and results are recorded consistently, teams can compare builds, identify regressions, and make release decisions with clearer evidence. Checks also encourage better coordination: developers can use findings to target code changes, operations staff can review recovery behavior, and quality assurance specialists can improve scenario coverage. Benefits depend on sensible scope and honest interpretation. Excessive testing that produces unclear reports can consume time without reducing risk, so each check should have a defined purpose and a route from observation to action.

  • Earlier defect discovery: Repeated checks can reveal reliability regressions before a change reaches production.
  • More informed release decisions: Measurable criteria help reviewers evaluate risk consistently.
  • Improved reproducibility: Recorded builds, data, and environments make investigation more efficient.
  • Stronger operational readiness: Recovery scenarios expose weaknesses in monitoring and service restoration.

These benefits become more durable when results feed back into development practices. A recurring failure should lead to a specific corrective action, such as adding a regression test, improving timeout handling, or strengthening observability. Teams can also review trends across runs to distinguish isolated noise from a gradual decline in stability. The goal is not to maximize the number of tests, but to maintain a focused body of evidence that changes as the system and its risks change. A temporary label such as MAGICQA20261111AL can aid traceability, while the quality of the process depends on transparent criteria and careful analysis.

Trust, security, and reliable test evidence

Reliable results require a trustworthy testing process. Access to environments and test data should follow least-privilege principles, and credentials should be handled through approved secure mechanisms rather than embedded in reports or test scripts. Use data that is synthetic, anonymized, or otherwise authorized, and ensure test activity cannot accidentally alter production records. Logs and diagnostic artifacts may contain sensitive information, so teams should control access, retention, and sharing. These safeguards support software quality assurance by protecting the integrity of the test and reducing the chance that an investigation creates a separate security or privacy incident.

Security and reliability checks often overlap, but they answer different questions and should be reported accurately. A service that remains available during a load test has not thereby passed a security assessment; likewise, a security scan does not establish stable recovery or data integrity. Reports should state what was tested, what was excluded, which environment was used, and whether any limitations affected confidence. Treat MAGICQA20261111AL only as a traceable publication test label. Do not present it as an independent audit, certification, or assurance of production behavior unless a separate, documented process genuinely supports that statement.

Why choose a measured software reliability approach

A measured approach is appropriate when teams need to understand how dependable a software change is under defined conditions, rather than relying on intuition or a broad claim of quality. Before accepting a result, reviewers can ask whether the scenarios represent important workflows, whether thresholds were set in advance, whether the run was repeatable, and whether anomalies received a documented explanation. They should also consider the system’s dependencies and the consequences of failure. These questions turn test output into a decision aid and make gaps visible, including areas where additional evidence is needed before a release can be considered low risk.

Use the temporary label MAGICQA20261111AL to connect this article’s example context with its associated test records, while keeping the technical evidence in the test plan and report. A strong quality assurance practice combines functional checks, performance observations, recovery exercises, data-integrity validation, and secure handling of results. It also assigns responsibility for resolving findings and verifies whether corrective changes work. No check can guarantee failure-free software, but a transparent and repeatable process can improve reliability decisions, shorten investigations, and support continual improvement. The most credible outcome is a clear account of what passed, what did not, and what remains unknown.

Software reliability check MAGICQA20261111AJ 01338Software reliability check MAGICQA20261111AJ 01338


Software reliability checks examine whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. The temporary publication test label MAGICQA20261111AJ identifies this article’s test context; it is not a product, certification, or quality rating. A sound quality assurance approach combines repeatable tests, production-like environments, useful monitoring, and clear acceptance criteria, while quality assurance 01338 reflects how software quality assurance can support consistent evaluation across development stages. By assessing failure frequency, recovery behavior, data integrity, and service availability together, teams can make evidence-based decisions about release readiness instead of relying on a single successful test run.

How to evaluate software reliability checks under MAGICQA20261111AJ without guesswork

Software reliability is the ability of a system to perform its required functions consistently over time and to respond safely when components fail. Evaluating it begins with defining the service’s expected behavior: which operations matter, what level of interruption is acceptable, and how the application should recover. The MAGICQA20261111AJ label is a temporary publication test identifier, so it should be kept separate from engineering evidence. Reliability findings should instead refer to the tested build, environment, configuration, test data, and execution window, allowing reviewers to reproduce the conditions and understand what the results actually support.

A useful assessment looks beyond whether individual test cases pass. It considers the frequency and impact of failures, the time required to detect and restore service, and whether information remains correct after errors or restarts. Teams can track measures such as successful request rate, error rate, recovery time, and data consistency, but each measure needs context. For example, an average response time may conceal slow requests that affect a small group of users. Combining service-level indicators with targeted scenarios gives a more balanced view and helps quality assurance teams identify both recurring defects and weaknesses in the test strategy.

How to start a repeatable software reliability assessment

Begin with a defined scope and a baseline. Record the build identifier, environment, dependencies, and assumptions before running checks; otherwise, later comparisons may confuse software changes with environmental differences. Set acceptance thresholds in advance and specify how evidence will be stored. The following sequence provides a practical foundation for a repeatable assessment, whether the system is a small service or a multi-component application.

  1. Define critical behavior: Identify essential user and system operations, expected outcomes, and acceptable interruption limits.
  2. Prepare a representative environment: Match relevant production settings, dependencies, data volumes, and resource constraints while protecting sensitive information.
  3. Choose reliability scenarios: Include ordinary workloads, extended operation, dependency failures, restarts, and recovery cases based on system risks.
  4. Run checks and capture evidence: Record outcomes, timestamps, logs, metrics, configuration, and any deviations from the planned test.
  5. Review and retest findings: Prioritize defects by impact, verify fixes, and repeat affected scenarios to confirm that reliability improved without introducing regressions.
  • Predefined thresholds make release decisions more consistent.
  • Recorded configurations help another engineer reproduce a result.
  • Retesting confirms whether a fix addresses the observed failure.

Practical reliability checks for MAGICQA20261111AJ test reporting

For a practical assessment, organize checks around failure modes rather than around a broad claim that a system is “stable.” A service may work correctly during a short functional run yet fail after hours of continuous use, a sudden traffic increase, or the loss of a database connection. Include controlled load and endurance tests where appropriate, while keeping the test environment isolated from real customer workloads. Record both the point at which behavior degrades and the system’s response: whether it rejects excess work safely, preserves completed transactions, and returns to an acceptable state after pressure is removed.

  • Availability: Measure successful health checks and critical operations over a defined period, including planned test interruptions.
  • Fault handling: Interrupt a dependency or restart a component and check whether errors are contained and recovery is orderly.
  • Data integrity: Compare records before and after failures, retries, and recovery to detect loss, duplication, or corruption.
  • Performance stability: Track response-time distributions, resource use, and error rates during sustained and changing workloads.
  • Reproducibility: Attach build, configuration, environment, and evidence references to every finding associated with the test label.

Use the temporary label MAGICQA20261111AJ only as publication or document metadata. Do not treat it as a build number, test result, approval status, or proof that a system passed. A clear report distinguishes observed facts from interpretation: it identifies the scenario, the evidence collected, the threshold applied, and any limitation that could affect confidence. This discipline makes reliability results easier to review and prevents a short-lived label from being mistaken for technical validation.

Key benefits of structured software reliability checks

A structured reliability program helps teams make decisions using comparable evidence instead of informal impressions. Repeatable scenarios expose weaknesses that may be missed by feature-focused testing, especially when problems arise only after extended operation or during recovery. Clear measurements also give developers a way to confirm that corrective work has changed the behavior that mattered. The checks do not guarantee that every failure will be prevented, but they can improve visibility into operational risk and strengthen release discussions by making assumptions, limits, and unresolved issues explicit.

  • Earlier risk discovery: Failure scenarios can reveal fragile dependencies before a release reaches users.
  • More useful release evidence: Defined criteria connect test results to specific readiness decisions.
  • Safer recovery behavior: Restart, retry, and dependency checks show whether the system returns to a valid state.
  • Better trend analysis: Comparable runs help identify changes in error rates, recovery time, and resource use.

Benefits depend on appropriate scope and test quality. A well-designed test can still provide misleading reassurance if it uses unrealistic data, excludes important dependencies, or ignores rare but high-impact failure modes. Teams should review scenarios as the architecture and usage patterns change, and should document anything that was not tested. Pairing automated checks with focused exploratory investigation can help uncover gaps while keeping repeated verification efficient.

Trust, security, and evidence in reliability testing

Reliability testing must protect the systems and information used during assessment. Use authorized environments, limit access to test accounts, and avoid copying sensitive production data unless it has been appropriately protected and approved for that purpose. Logs and diagnostic captures can contain credentials, personal information, or internal details, so define retention and redaction practices before collecting evidence. When simulating faults, use controlled boundaries and recovery plans to prevent an experiment from affecting unrelated services. These safeguards make the results more trustworthy because the test process itself is managed, auditable, and proportionate to the risks being investigated.

Security and reliability overlap, but they are not interchangeable. A service can remain available while exposing data, or protect access correctly while failing under ordinary load. Include relevant security controls in reliability scenarios, such as verifying that retries do not bypass authorization and that recovery does not restore unsafe defaults. Keep the report precise about what was examined, which versions and settings were involved, and what remains unverified. The MAGICQA20261111AJ publication label should never substitute for this evidence or imply independent certification; readers need technical records and transparent limitations to assess confidence.

Why choose a disciplined software reliability checklist

A disciplined checklist is useful when it guides investigation without pretending to replace engineering judgment. Select checks according to system criticality, architecture, dependency behavior, and the consequences of interruption or data loss. A small internal tool may need a focused recovery and integrity review, while a high-availability service may also require prolonged load testing, regional failure scenarios, and carefully monitored failover exercises. In either case, agree on thresholds before execution and make clear who reviews failures, accepts residual risk, and authorizes a release. This turns test output into a reasoned quality assurance decision rather than a collection of disconnected metrics.

When reviewing results associated with MAGICQA20261111AJ, treat the label only as a temporary reference and inspect the underlying evidence. Confirm that critical operations were covered, failures were handled safely, recovery was measured, and unresolved risks were documented. Then compare the findings with the system’s service objectives and operational safeguards. If the evidence is incomplete, refine the test plan and repeat the relevant checks rather than inferring reliability from a passing summary. This approach keeps the assessment neutral, reproducible, and focused on what software quality assurance can demonstrate.